SQL against CSV, TSV, LTSV, JSON, JSONL, Parquet, Excel, ACH, and Fedwire
sqly runs SQL against CSV, TSV, LTSV, JSON, JSONL, Parquet, Excel, ACH, and Fedwire files. It loads them into an in-memory SQLite database, so joins, CTEs, window functions, and aggregates all work — across formats, in one query.
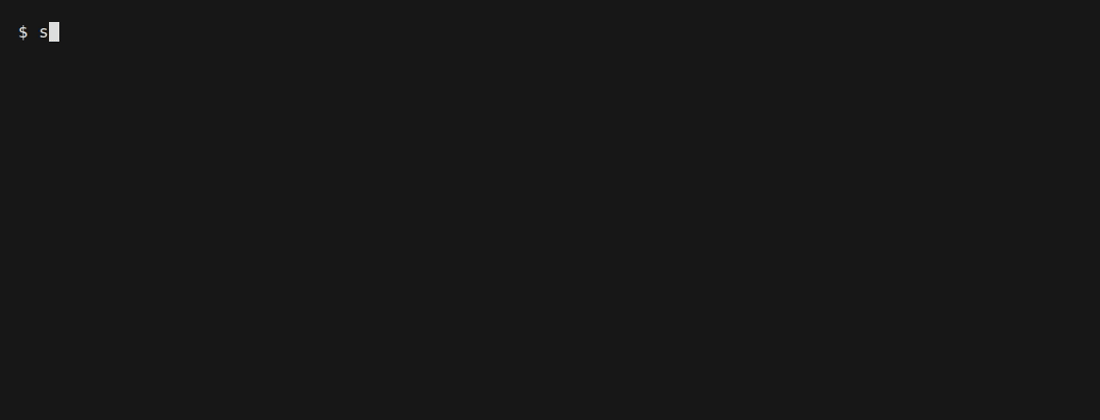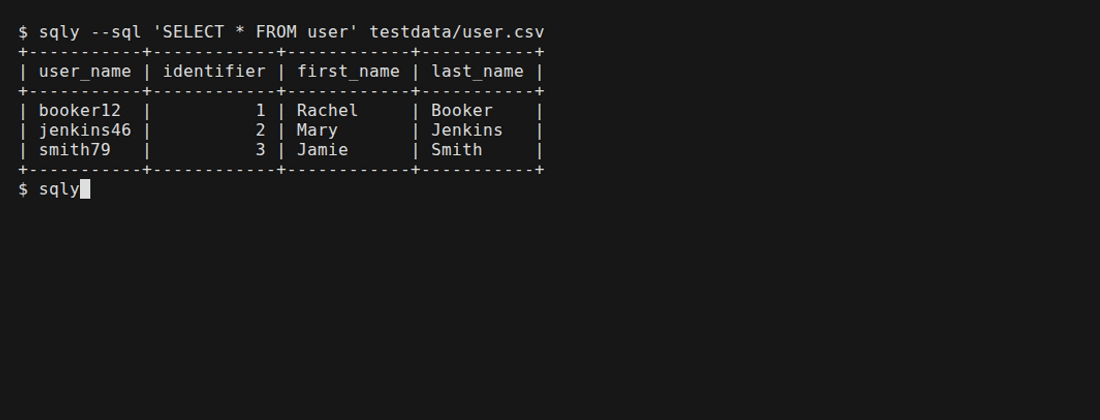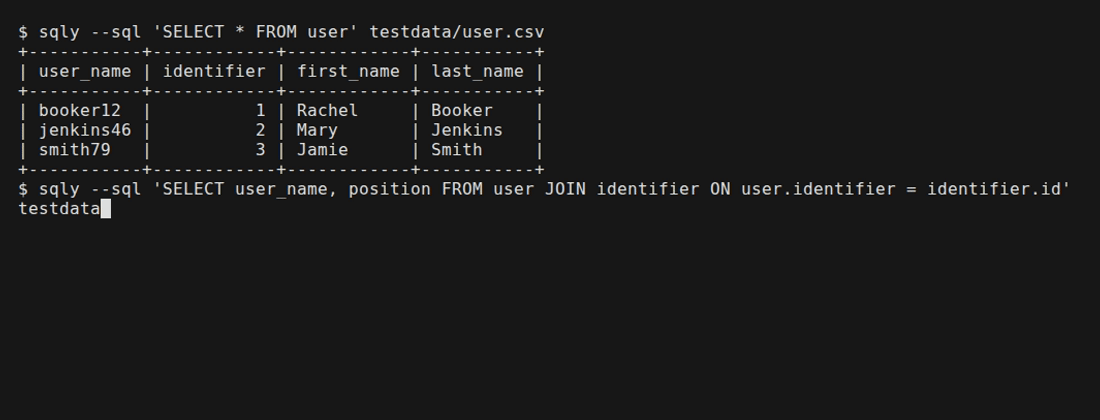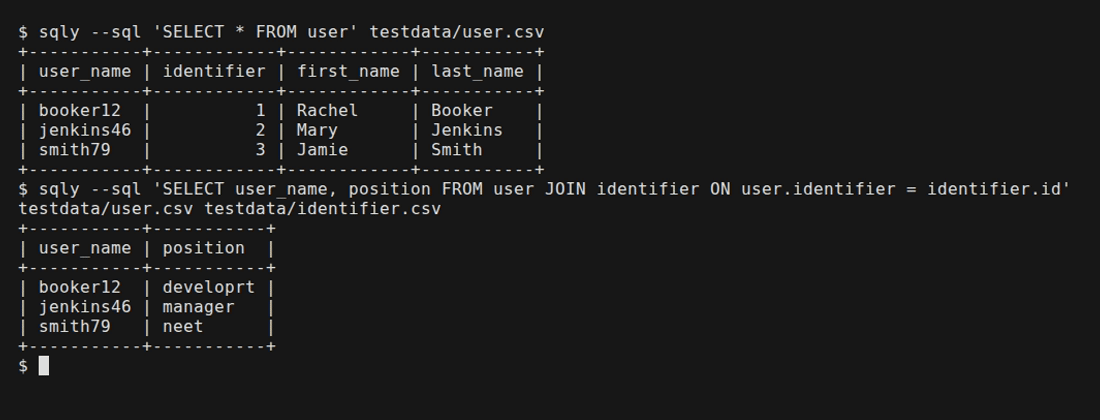
Try it in 30 seconds #
printf 'name,dept,salary\nalice,eng,120\nbob,sales,90\ncarol,eng,140\n' > staff.csv
go run github.com/nao1215/sqly@latest --sql "SELECT dept, ROUND(AVG(salary)) AS avg FROM staff GROUP BY dept" staff.csv
+-------+-----+
| dept  | avg |
+-------+-----+
| eng   | 130 |
| sales |  90 |
+-------+-----+
The file is the table: staff.csv became staff. Nothing to declare, no schema to write.
Three things to try next #
sqly --output-format json --sql "SELECT * FROM staff" --output staff.json staff.csv   # convert
sqly --sql "SELECT * FROM a JOIN b ON a.id = b.id" a.csv b.parquet      # join across formats
sqly staff.csv                                                          # open the shell
The cookbook has the rest: JSON extraction, Excel sheets, HTTP inputs, inspecting data, writing changes back, and MySQL/PostgreSQL/BigQuery syntax.
It reads and writes a pipe #
sqly is a filter, not a destination. It takes standard input, and its non-table output is meant for the next command:
curl -s https://example.com/sales.csv | sqly --stdin-format csv --sql "SELECT region, SUM(amount) FROM stdin GROUP BY region"
sqly --output-format jsonl --sql "SELECT path FROM logs WHERE status >= 500" logs.csv | jq -r '.path'
sqly --output-format tsv --sql "SELECT status, path FROM logs" logs.csv | cut -f1 | sort -rn | head -n 1
Filter in SQL, shape in jq: SQL has the WHERE, GROUP BY, and JOIN, so jq only ever sees the rows that matter. For nested JSON, json_extract reaches into the document and sqly can stand in for jq entirely. A failed query exits non-zero, so set -e works. Pipe data out has the details.
Why sqly? #
Pick the tool that fits the job:
| You want | Use |
|---|---|
| A field-oriented text processor for logs and columns | awk, Miller |
| A CSV-native SQL dialect with its own engine and cursors | csvq |
| SQL over CSV/TSV/JSON with a choice of backend engines | trdsql |
| SQL over CSV with mature Python tooling | q, textql |
| SQL over files, with an interactive shell, cross-format joins, and write-back | sqly |
sqly’s own emphasis is the session: an interactive shell with completion and history, files of different formats joined as peers, and the ability to write your edits back into the source file.
The shell #
sqly with no --sql opens a REPL. Tab completes keywords, table names, and paths; history persists across sessions; dot-commands cover the things SQL has no syntax for.
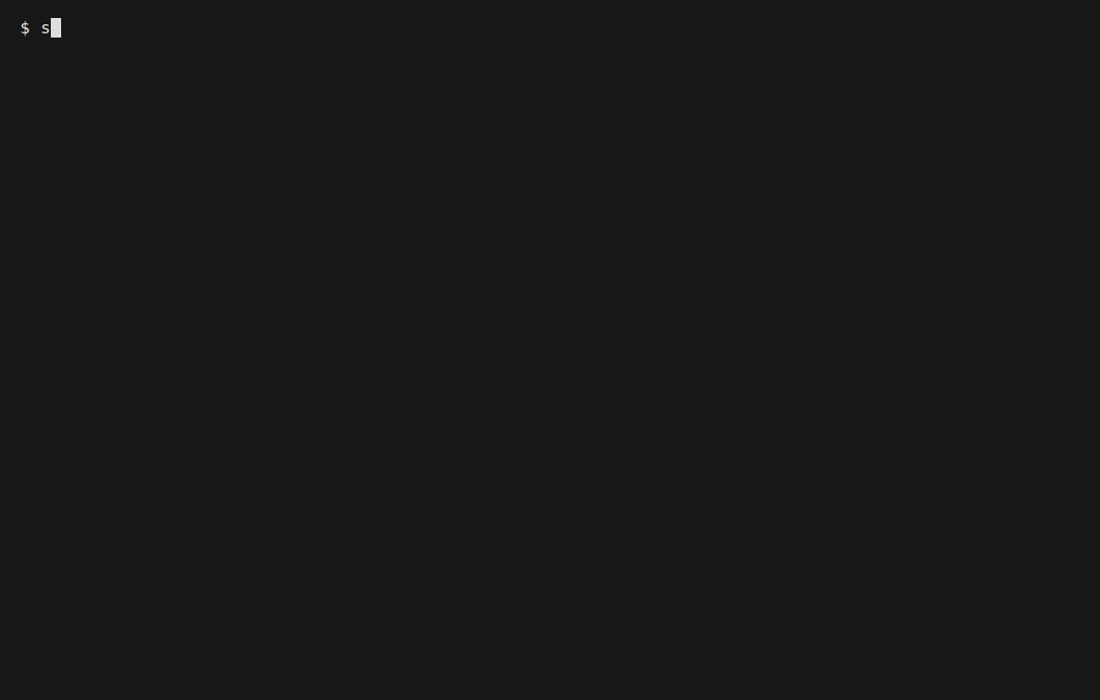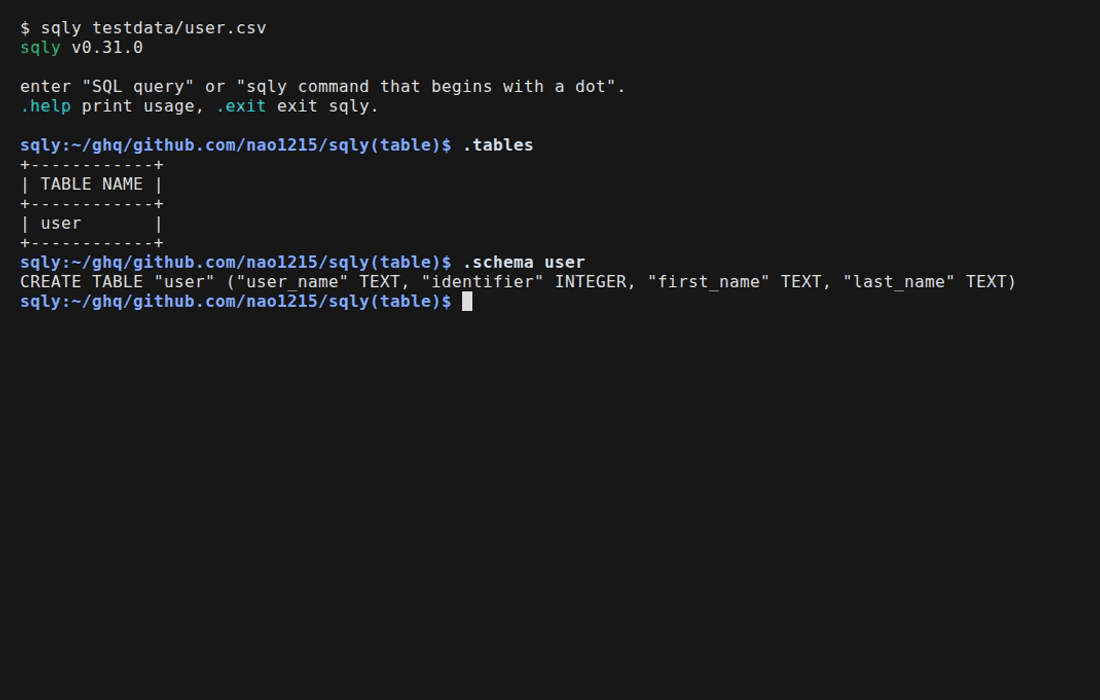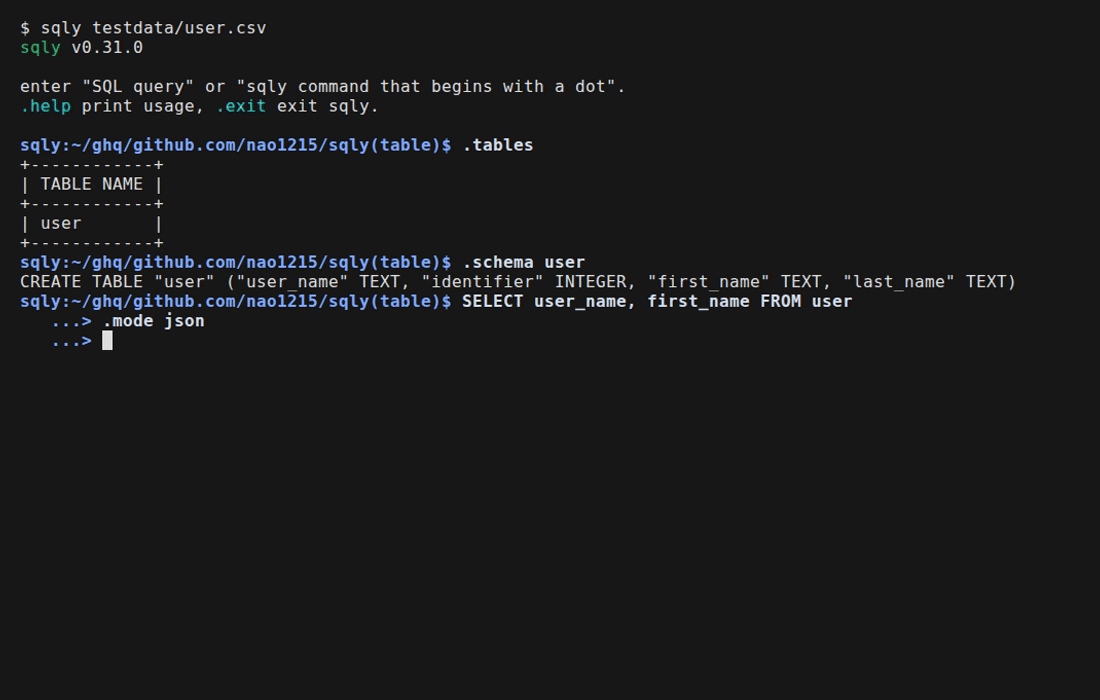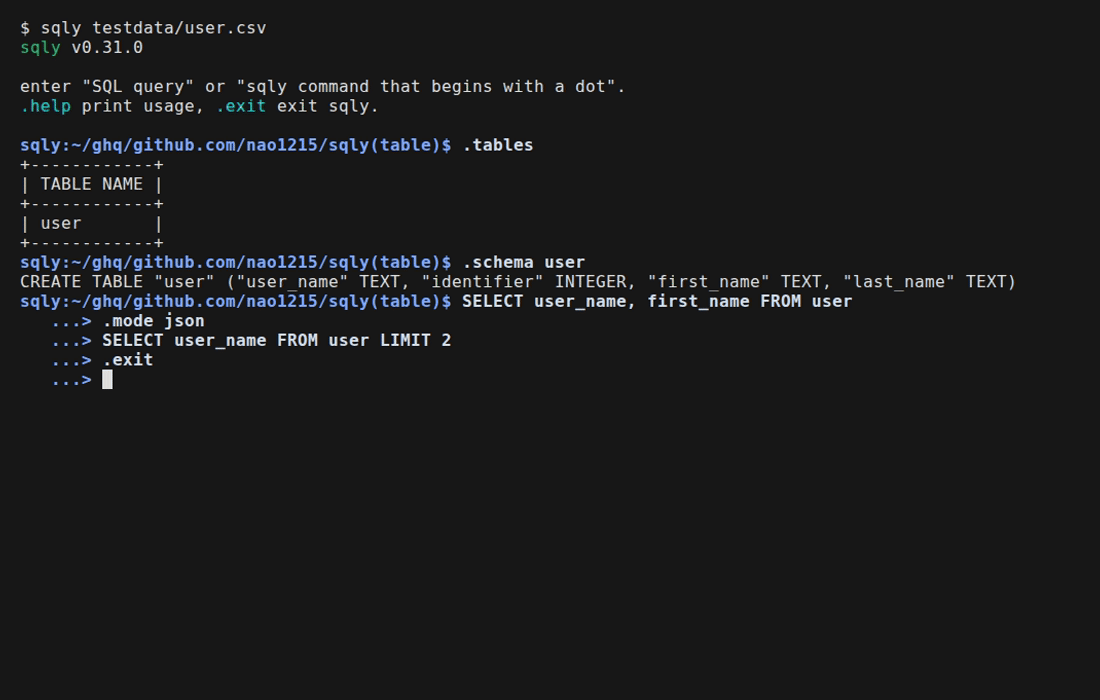
sqly:~/data(table)$ .import user.csv
sqly:~/data(table)$ SELECT user_name FROM user
   ...> WHERE identifier = 1;
sqly:~/data(table)$ .mode json
sqly:~/data(json)$ .save ./out
See Shell for every dot-command.
Install #
go install github.com/nao1215/sqly@latest
Homebrew, the AUR, aqua, mise, and prebuilt binaries are on the install page.